About DataHerb
A metadata-driven data catalog that never takes your data.
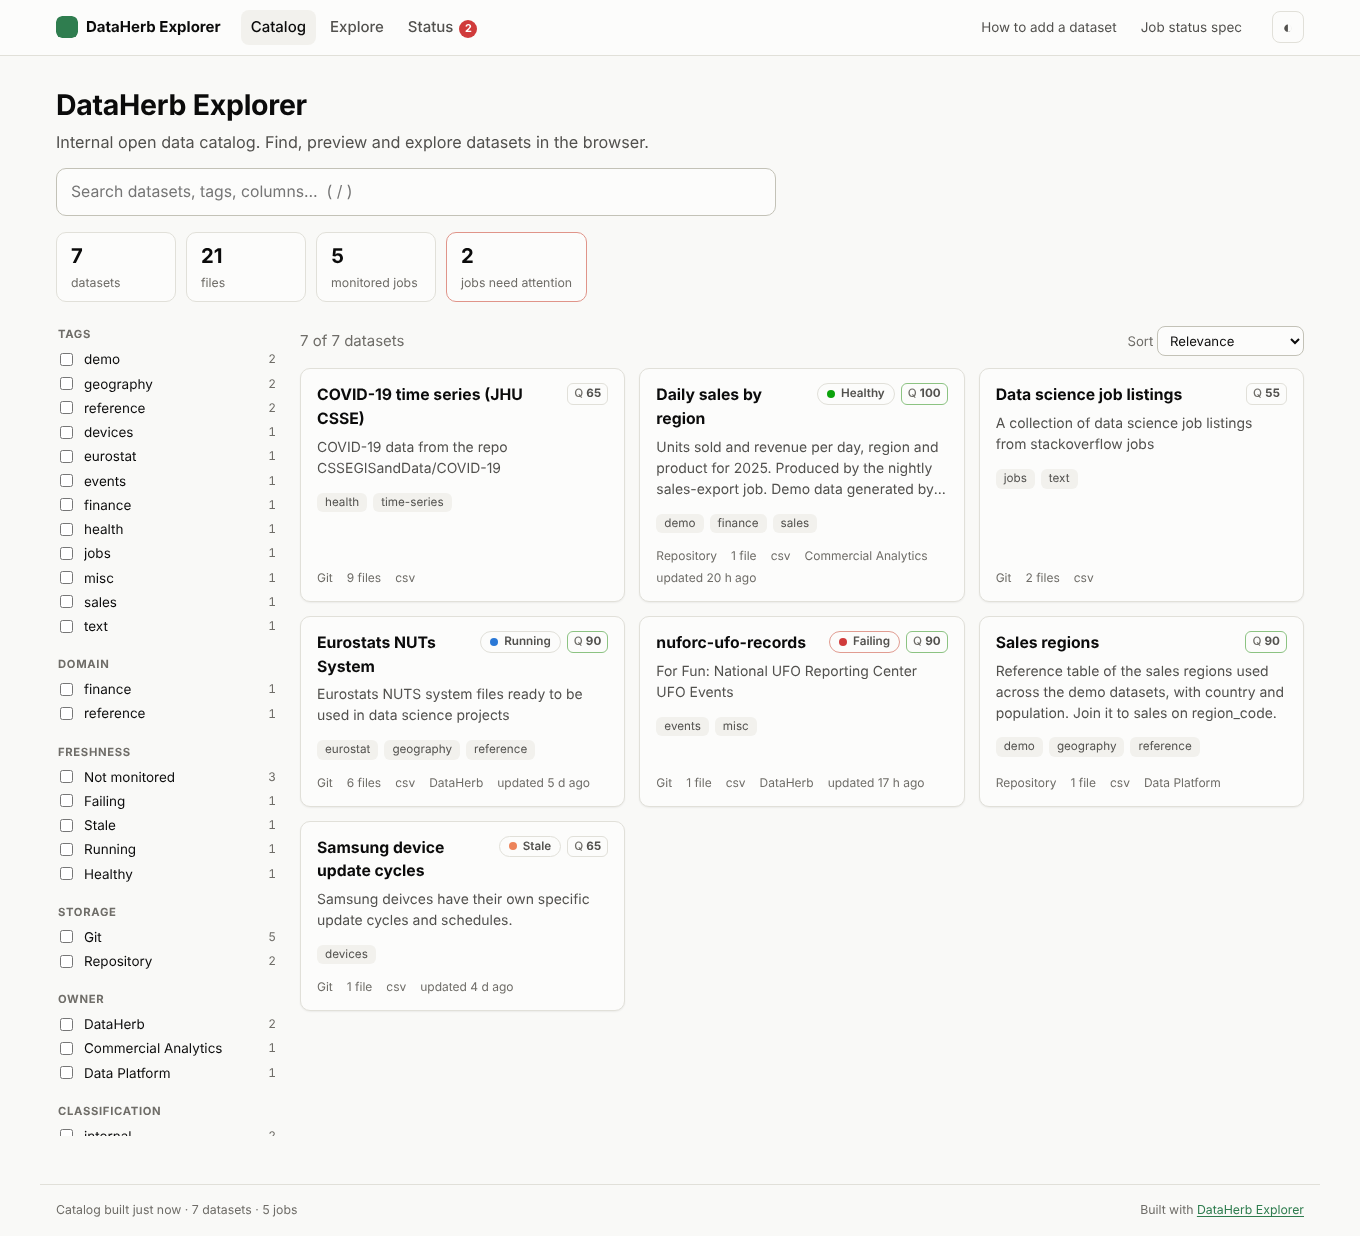
DataHerb is a metadata-driven data catalog. Version 2 is DataHerb Explorer: a catalog and explorer for an organization’s open data that is just a static website, configured by one YAML file and deployed on GitHub Pages or S3.
How Does It Work
DataHerb does not take your data. Datasets stay where their owners keep them, in git repositories, S3 buckets, web folders or the catalog repository, each described by a dataherb.yml next to the files. The catalog is a folder of small Markdown files, one per dataset, reviewed through pull requests.
A scheduled GitHub Actions job runs dataherb catalog build, which reads dataherb.config.yml and the catalog and writes a static site. In the browser, DuckDB-WASM reads the data files directly for previews, SQL and charts, and pipelines report their runs as status files the site reads live. There is no server and no database.
How to Contribute
- Run DataHerb Explorer for your team: Get started.
- Add an open dataset to the public catalog: Add a dataset.
- Write a short story about the story behind your dataset and submit it to DataHerb Articles.
- Help build a better DataHerb on GitHub.
What Changed in v2
- The website and the Flora index are replaced by a forkable static explorer, so any organization can run its own catalog.
- Datasets can live in git, S3, HTTP or local folders, not only GitHub.
- In-browser exploration with DuckDB-WASM: SQL, joins, charts and profiling.
- Job status monitoring with the
dataherb.status/v1spec. - The
dataherbCLI gaineddataherb cataloganddataherb statuscommands and installs with uv. - v1 metadata (
dataherb.json,.dataherb/metadata.yml) is still read. The v1 Flora stays online for reference.
From v1 to v2
| v1 | v2 |
|---|---|
dataherb-flora (a YAML listing per dataset) |
catalog/ folder of Markdown entries, plus S3, HTTP and local sources and discovery |
dataherb-metadata-aggregator |
dataherb catalog build (aggregation, validation, linting) |
| This Jekyll site’s Flora pages | The explorer’s static app with preview, SQL explorer and status |
dataherb create / upload |
dataherb create infers the schema; dataherb catalog and dataherb status added |
dataherb.json, .dataherb/metadata.yml |
Read as is; v2 adds owner, tags, license, classification, update frequency, status job and related datasets |
Acknowledgement
The v1 Flora pages use art from unDraw and a terminal adapted from the MIT licensed Portfolio - Type help.